
 Delivered by Eco-Flow
Nextflow: Reproducible Scientific Workflows at Scale
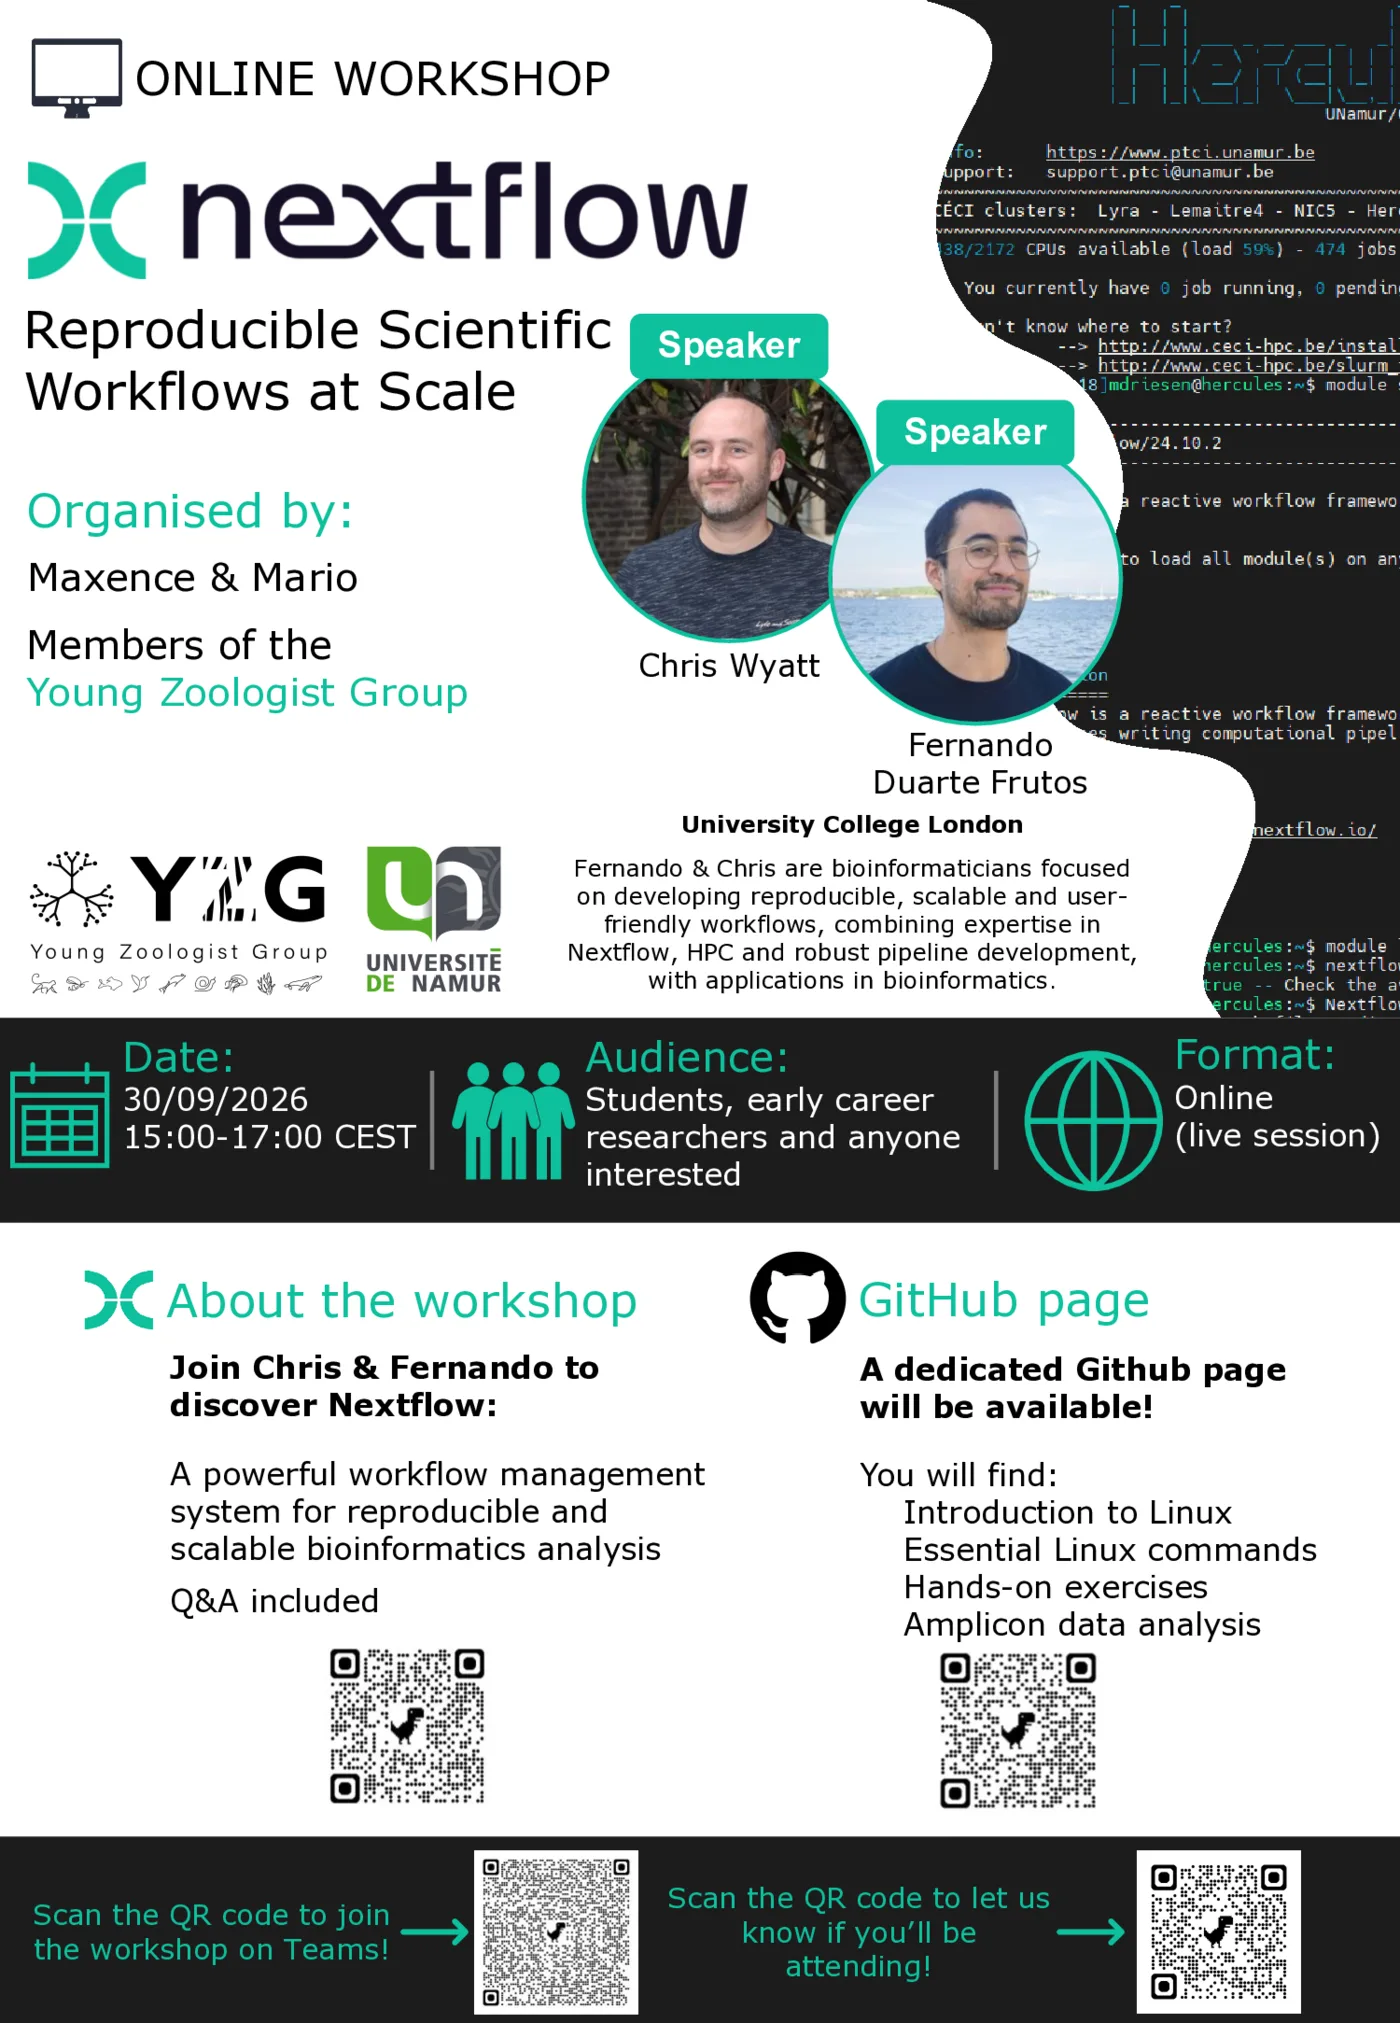
On Wednesday 30 September 2026, 15:00–17:00 CEST, we ran Nextflow: Reproducible Scientific Workflows at Scale, a live online workshop over Microsoft Teams for the Young Zoologist Group in Belgium. It was organised by Maxence and Mario, members of the group, with the Université de Namur.
What it was about
The workshop introduced Nextflow and nf-core. We explained why pipelines matter for reproducible science and showed how the same analysis can run on a laptop or scale up to an HPC cluster.
Attendees worked through our hands-on exercises from the Eco-Flow training course, which runs in the browser through GitHub Codespaces:
- Amplicon data analysis: running the nf-core/ampliseq pipeline on 16S data from river and soil samples, from raw reads to taxonomic classification, diversity statistics and a QC report. We made this lesson especially for this course.
- Running a pipeline on an HPC: running an nf-core pipeline on a Slurm or SGE cluster, including getting the pipeline, submitting and monitoring jobs, keeping Nextflow running, and avoiding common mistakes. Attendees practised on a mini Slurm cluster inside Codespaces.
The session finished with a Q&A.
Who it was for
Students, early-career researchers and anyone curious about building reproducible analyses. No prior Nextflow experience was needed.
The poster
Keep learning
All of the workshop material stays online, so you can work through it at your own pace. The full training course goes further, with a command-line primer, an RNA-Seq practical, differential expression in R, nanopore metabarcoding and monitoring runs with Seqera Platform.
Thank you to Maxence, Mario and the Young Zoologist Group for inviting us, and to everyone who joined. For questions, contact us at ecoflow.ucl@gmail.com.